AI models
Benchmark: the same test for every model
Settings > Benchmark (desktop app) runs the same test on any model here: a local one or a cloud model.
What it measures
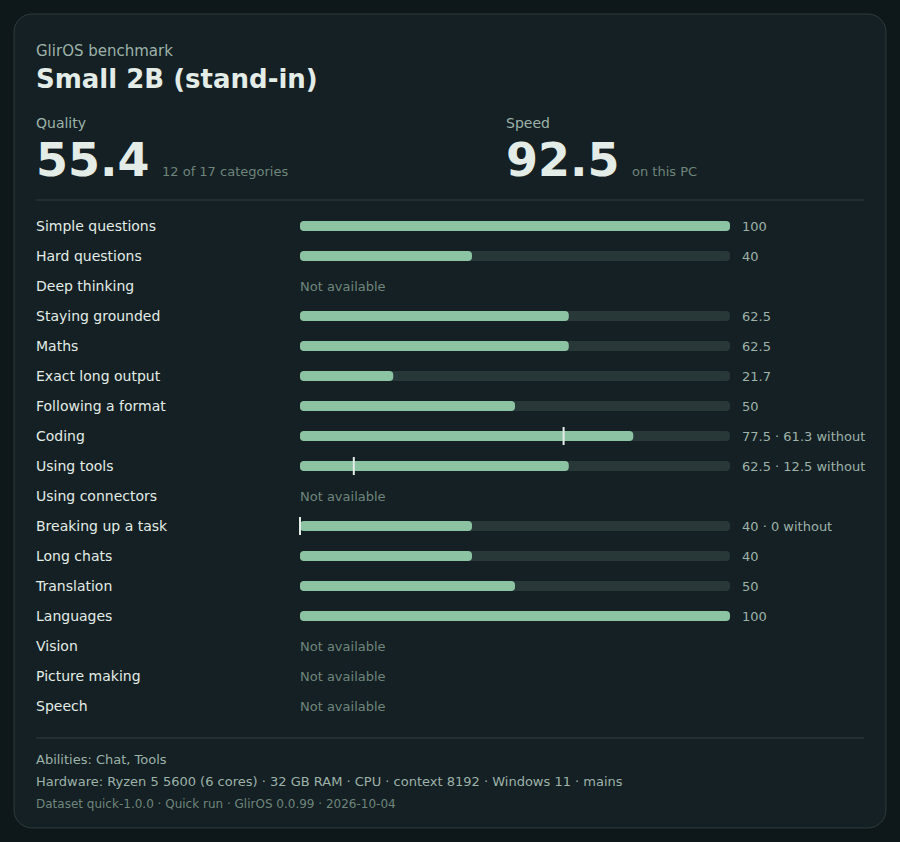
It gives two scores, Quality and Speed (speed is on this PC), and one line per category:
- simple and hard questions
- deep thinking
- staying with the given text
- maths
- exact long output
- following a format
- coding (the code is run and tested)
- using tools
- breaking up a task
- long chats
- translation and languages.
Coding, tools and plans show their score with GlirOS's help and without it.
Running a test
The quick run takes a few minutes on a graphics card. The test texts are written for GlirOS and hold nothing of yours; tools answer from fixed stand-ins, and nothing goes into your chats. While it runs, chatting waits.
A cloud model asks first and shows the estimated tokens; the result shows what the provider counted.
Comparing results and presets
Results can be compared, exported (picture, file, text, table) and imported from another PC. Under it, the presets pack tests one model on GlirOS's own suggestions, every tool's first examples and whether it calls only the tools that are there, with and without GlirOS's help; its own table and an export, outside the scores.
This guide is the same text GlirOS itself uses to answer questions about GlirOS.